 FUTURE PROOF MARKETER
Artificial IntelligenceMarketing
Best LLM Gateways (2026): What an AI Gateway Is, and the 7 Worth Using
Some links below are affiliate links: if you buy through them we may earn a commission at no extra cost to you. It funds the testing budget and never changes a verdict — affiliate policy.
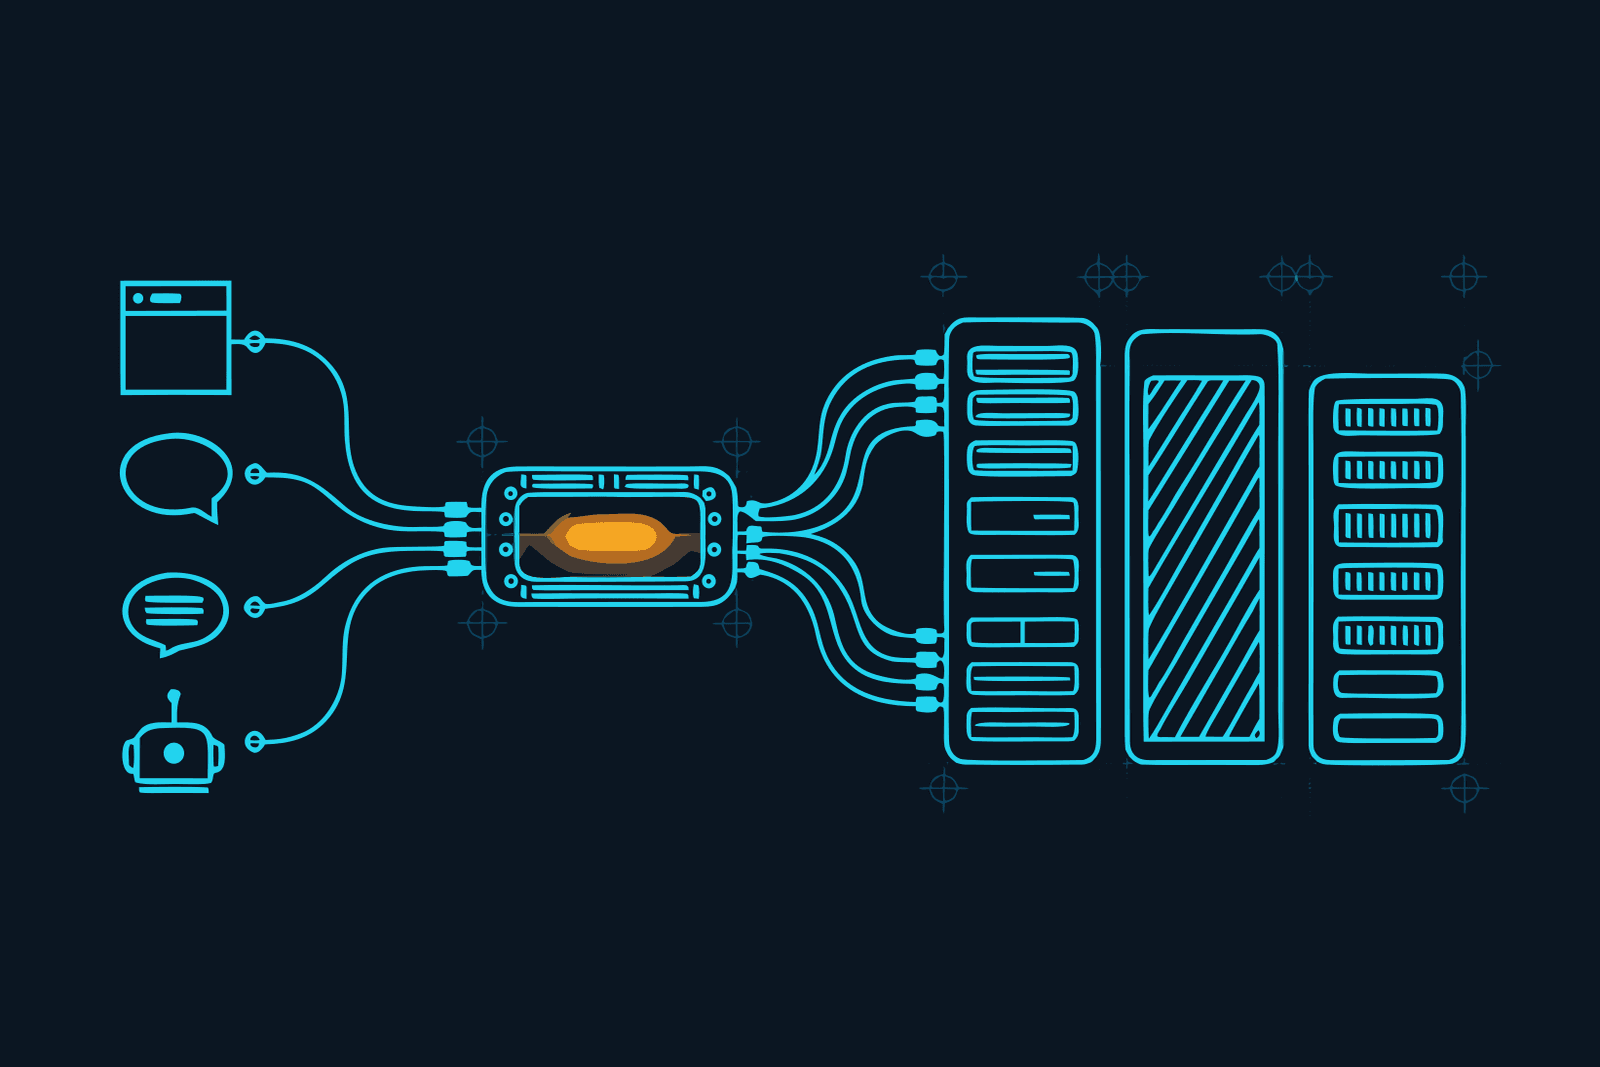
An LLM gateway, also called an AI gateway, is one address that sits between your apps or AI agents and the model providers they call. Instead of each tool talking straight to OpenAI or Anthropic, it talks to the gateway, and the gateway routes the request, counts the cost, applies your rules and keeps the log. Which one to use depends on the job: Constellation Gate AI if your AI reads outside material or you need a record you cannot edit, Vercel or Cloudflare for zero-markup routing, Portkey for a guardrails console, LiteLLM or Kong to run it yourself, and tamp for fewer tokens from a coding agent on your laptop. Everything below was checked on the vendors' own pages on 23 September 2026.
Searches for "llm gateway" have roughly quadrupled in a year, for a plain reason: once you have more than one AI tool, or one that reads e-mail and web pages, "what did it send, what did it cost, and who checked it" has no answer unless something sits in the middle.
What an LLM gateway actually does
Strip the marketing and a gateway does up to five jobs. No product on this list does all five equally well, which is why the choice matters.
- Routing. One key, one endpoint, many models. Fall back to another provider when one is down, or send cheap tasks to a cheap model.
- Cost control. Track spend per key, project or person, and stop it at a limit. A loop does not know it is a loop; a cap does.
- Security. Screen requests and responses for prompt injection, strip personal data and credentials before they leave or come back.
- Evidence. Keep a log. Some are debug logs you can read; a few are records you could hand a client or an auditor.
- Efficiency. Cache repeated requests, or remove duplicated content before it reaches the model so you are billed for less.
Most gateways were built for the first two. The category is moving to the last three, because agents now read things nobody on your team wrote; our prompt injection explainer shows how that goes wrong.
LLM proxy, AI gateway, LLM middleware: the same seat, different jobs
The vocabulary is a mess, so here is how we use it.
An LLM proxy forwards requests. Point your tool's base URL at it and it passes the call to the real provider. The simplest proxies do nothing else; tamp, further down, is a proxy with one job (compression).
LLM middleware is the logic that runs on a request while it passes through: authentication, retries, caching, redaction, limits, logging. It can live inside your own code as a library or outside it as a service.
An AI gateway is middleware run as a separate service, usually with a dashboard, so every tool pointed at it gets the same rules. That last part is the real reason to use one: you set a policy once instead of rebuilding it in each app, agent and teammate's laptop.
For people who do not write code, the useful mental model is a change of address. Your tools stay, your logins stay, and you change where they send the request. We walk through exactly that for Claude Code and OpenCode.
What an OpenAI compatible proxy changes, and what it does not
Most gateways accept requests in OpenAI's format and translate them for other providers, so one SDK can call Claude, Gemini and Llama with a single base URL and key. Switching models then costs minutes, not a rewrite. Two things to check first:
- Not every tool speaks OpenAI's format. Claude Code talks Anthropic's Messages API. A gateway that only accepts the OpenAI shape cannot sit in front of it without a translation layer. Check that the gateway accepts the format your tool actually sends.
- Translation is not free of edge cases. Provider-specific features (Anthropic's prompt caching headers, tool-use details, streaming quirks) need to survive the round trip. Read the gateway's docs for the one feature you depend on.
Before you pick a product: do the free things first
A gateway is not the first fix for every problem. Whatever you choose, these cost nothing and work today:
- Set a spend limit in the provider console. OpenAI and Anthropic both offer one. It is crude, but it stops the worst night.
- Use the provider's own prompt caching. On long, repeated contexts it is the largest single saving available, and it needs no gateway.
- Give agents only the tools they need. An agent that cannot send e-mail cannot be tricked into sending e-mail. Our seven defences against prompt injection start here, not with a product.
- Use a smaller model for routine subtasks. Summaries, classification and subagents rarely need the frontier model.
- Write down which tools talk to which models. Most small teams cannot, and that list is the first thing any gateway will show you anyway.
If those cover you, you may not need a gateway yet. If you want screening, a record, per-person caps or fewer tokens per request, read on.
Multi model API gateway comparison
Fees and features as published on each vendor's own pages on 23 September 2026. "Fee on top" means what is added to the provider's list price when you pay through the gateway.
| Gateway | What it is | Fee on top of provider price | Open source | Screens for prompt injection | Log | Free tier |
|---|---|---|---|---|---|---|
| Constellation Gate AI | Hosted security and accountability gateway | 0% ("the same price you would pay the provider directly"); or bring your own keys | No | Yes; flags on Free, blocks on Pro | Hash-chained, anchored audit trail | 20,000 recorded requests/mo |
| Portkey | Hosted gateway with guardrails console, plus open-source core | None stated; plan fee instead | Gateway core, MIT | Guardrails; deterministic on free, LLM and partner guardrails on $49 | 10k logs free, 100k on $49 | Developer plan, free |
| LiteLLM | Self-hosted OpenAI-compatible proxy | 0% (you host it) | Yes, MIT | Guardrails you configure | Your own database and tools | Open source, no licence fee |
| Cloudflare AI Gateway | Hosted gateway on Cloudflare's network | 0% with your own keys; 5% on Unified Billing credits | No | Guardrails billed as Workers AI inference; DLP free | 100k logs free, 10M per gateway paid | Core features free |
| Vercel AI Gateway | Hosted multi-model gateway | 0%, "no markup and no platform fee on tokens"; card fees apply | No | No | Traces as a paid add-on | Monthly free credit, subset of models |
| Kong AI Gateway | AI plugins for Kong's API gateway | Not a token reseller | AI plugins free and open source since Gateway 3.6 | Regex allow/deny prompt guard | Via Kong's logging and analytics | OSS; Konnect 30-day free trial |
| tamp | Local compression proxy for coding agents | None, runs on your machine | Yes, MIT | No (masks secrets by default) | Local log to stderr or file | Free |
The honest reading: if your problem is routing and fees, four of these solve it. If your problem is what the AI read, what it did and whether you can prove it, the list gets much shorter.
The seven, one by one
Constellation Gate AI
Constellation Gate AI is the gateway on this list that starts from security and accountability rather than routing. Affiliate link: we earn a commission on Pro seats at no cost to you, and it pays for the testing, not the verdict. It calls itself "the accountability layer for AI" and sits "between your agent and the model". The gateway lives at gateway.constellationgate.ai; for tools like Claude Code, Codex, OpenCode, Cursor, Claude Desktop, ChatGPT and Gemini, the Gate Connect menu-bar app does the change of address for you.
Every request and every response is screened for prompt injection, with a verdict per request: allowed, flagged, blocked or redacted. Gate's own figures, from its arXiv report (2606.02959): 95.4% of attacks caught at a 1% false-positive cap, 97.4% F1, with a 53 ms median screening time. Each request is also written into a hash-chained audit log anchored to Constellation's Digital Evidence layer. That is the difference between a debug log and a receipt: you can show someone what was sent, and they can check nobody edited it afterwards.
It also sends less. Gate removes repeated file reads and duplicated context before forwarding, losslessly, keeping the first copy of everything. Vendor-published: 20% or more fewer tokens on agent workloads, and 23% lower token cost in its Rocket Resume case study. Its cache is exact-match (a repeated identical request is answered from cache), not semantic. We are running our own sessions through it and publish our numbers on 30 September; until then, treat these as Gate's figures, not ours.
You pay for tokens either through Gate, at what it states is "the same price you would pay the provider directly", or with your own keys. It can also sit in front of a Claude Code subscription via a custom header, which almost nothing else here does. Free is $0 with 20,000 recorded requests a month, basic compression and the audit trail. Pro is $20 per user per month and adds injection blocking, PII and credential redaction, spend limits and full compression. Our full Gate review has the benchmarks and the trade-offs.
Best for: anyone whose AI reads outside material, anyone who will be asked what the AI did with a client's data, and small teams who want every seat's AI traffic in one place (the team rollout plan).
Try it on one tool. Start free with Gate: no card, one change of address, and your first requests show up in the log within minutes. Free records, Pro blocks: the free plan shows you a flagged request; stopping it is Pro.
Portkey
Portkey is the most complete "control panel" on the list. The hosted product has a free Developer plan with 10,000 recorded logs a month and deterministic guardrails, a Production plan at $49 a month with 100,000 logs (overage $9 per additional 100,000) and LLM and partner guardrails, and Enterprise on request. The gateway core is open source under MIT, routes to 1,600+ models across 40+ providers, advertises 50+ guardrails, and runs locally with one npx command.
No token markup is stated; the plan fee is the cost. If you want prompt management, fallbacks and a guardrails menu in one dashboard, and you are comfortable wiring those guardrails yourself, Portkey is a strong choice.
Best for: product teams building an AI feature who want a console more than a security layer.
LiteLLM
LiteLLM is the default ai api gateway open source answer. It is MIT-licensed, self-hosted, and speaks one OpenAI-compatible API to more than 140 providers. The open-source version already includes virtual keys, users and teams, spend tracking, budgets and rate limits, fallbacks and request logging. Guardrails for PII masking, prompt-injection detection and secret detection are available as integrations you configure. Enterprise is priced, in LiteLLM's words, by "annual gateway request capacity, deployment architecture, and support needs, never per token."
The cost is not money but ownership. There is no one to call, the server is yours to patch, and a gateway has to keep up with the tools it fronts. If you have an engineer who wants the proxy inside your own network, it is hard to beat.
Best for: technical teams who want full control and will run it.
Cloudflare AI Gateway
Cloudflare's gateway is free for its core features: dashboard analytics, caching and rate limiting. The free plan keeps 100,000 logs in total across all gateways; paid Workers plans keep 10 million per gateway. Bring your own provider keys and there is no fee. Buy credits through Unified Billing and Cloudflare adds 5% on the purchase ($100 of credit costs $105), while inference is passed through at the provider's price. Data-loss-prevention scanning is free on all plans; guardrails run on Workers AI and are billed as inference.
Best for: anyone already on Cloudflare who wants caching, rate limits and analytics for free.
Vercel AI Gateway
The cleanest fee story on the list. Vercel states that "AI Gateway charges no markup and no platform fee on tokens", including when you bring your own key, though bring-your-own-key needs the paid tier (you buy credits first) and you pay any card-processing fees. Budgets per team, project, key or member are built in. The free tier is a monthly credit on a subset of models with lower rate limits. Extras such as custom reporting, a team-wide provider allowlist and trace drains are paid add-ons.
It routes and meters well; it does not present itself as a security layer.
Best for: developers who want one key for many models at list price, especially if they already deploy on Vercel.
Kong AI Gateway
Kong turned its widely used API gateway into an AI gateway with a set of AI plugins, and in its own announcement said they are "entirely free and open source for everyone" from Kong Gateway 3.6. AI Proxy translates OpenAI-format requests to providers including OpenAI, Anthropic, Gemini, Bedrock, Mistral and Ollama. AI Prompt Guard filters prompts against regular-expression allow and deny lists, which catches patterns you already know about, not novel injection attempts. The hosted Konnect platform has a 30-day free trial; its Plus plan is billed per gateway per month, and Enterprise is custom. We could not find a published per-gateway figure on Kong's pricing page.
Best for: organisations already running Kong for their APIs who want AI traffic under the same roof.
tamp
tamp is not a gateway in the full sense, and it is on this list because people searching for one often want what it does. It is an MIT-licensed proxy you run on your own machine (npx @sliday/tamp, listening on localhost port 7778) that compresses what coding agents send: tool output, JSON, repeated content. It works with Claude Code, Codex CLI, OpenCode, Aider, Cursor, Cline, Windsurf and any OpenAI-compatible agent. Its own README claims 52.6% fewer input tokens, and 60 to 70% combined with output compression, across nine compression levels. It masks API keys, JWTs and PEM blocks by default. There is no hosted service, no dashboard beyond a local log, and no prompt-injection screening.
Its higher levels include optional stages that change content (one rewrites text with an LLM via OpenRouter when configured), so test them on real work first. And a local proxy covers one laptop, not a team.
Best for: a solo developer who wants fewer tokens from a coding agent and nothing else.
AI API gateway open source vs hosted: the real trade
Four of the seven have an open-source route: LiteLLM, Portkey's core, Kong's AI plugins and tamp. Open source removes the fee and keeps traffic on infrastructure you control. It does not remove the work: upgrades, uptime, keeping pace with new model APIs and wiring your own guardrails and log storage.
A hosted gateway trades that work for a vendor relationship. Ask "who will notice when it breaks at 11pm", not "which is cheaper". For a one-person business or small agency, that usually means hosted with a free tier now, self-hosted when you have someone to run it. Our OpenRouter alternatives comparison covers the pure routing side of this in more detail, including Requesty and Helicone.
Which one
- Your AI reads web pages, e-mail, PDFs or tool output you did not write: Gate. Screening is its first job, not an add-on.
- You will be asked what the AI did with a client's data: Gate, for the log nobody can edit afterwards.
- You run Claude Code, Codex or OpenCode and want it fronted without giving up the subscription: Gate, via Gate Connect.
- You want one key for many models at list price: Vercel AI Gateway, or Cloudflare with your own keys.
- You want caching and rate limits for free on infrastructure you already use: Cloudflare.
- You are building an AI feature and want a guardrails and prompt console: Portkey.
- You want it inside your own network and have an engineer to run it: LiteLLM.
- You already run Kong for your APIs: Kong AI Gateway.
- You only want fewer tokens from a coding agent on one machine: tamp.
- One provider, no agents, nothing sensitive: no gateway yet. Use the provider console and the free fixes above.
Your first fifteen minutes
Following the rule we apply to every tool: real input, one output, hard stop.
- Minutes 0 to 3. List every AI tool you used last week and which model each one calls. If you cannot finish the list, that is your first finding.
- Minutes 3 to 6. Pick one reason from "Which one" above. Only one.
- Minutes 6 to 11. Create a free account on the gateway that reason points to and point the tool you used most yesterday at it. For most readers of this site that is Gate: no card, and Gate Connect handles Claude Code, Codex and Cursor in one toggle. If you want to know what it is worth first, run your numbers in the calculator.
- Minutes 11 to 15. Do one real task through it. Open the dashboard and write down three things: requests recorded, cost, and anything flagged. Stop.
Output: one tool behind one gateway, and three numbers on a sticky note. A week later, look again. If you chose Gate for security, the number you are waiting for is the first flagged request. Free records, Pro blocks: the day you see one is the day the $20 Pro seat becomes a simple decision. Start free with Gate (affiliate link; we earn a commission on Pro seats).
Fees and features checked on each vendor's own pricing page, documentation or repository on 23 September 2026. Gate's security and compression figures are vendor-published; our own field-test numbers follow on 30 September. Gateways change their pricing often; if a number above is out of date, tell us and we will fix it with a dated note.
Questions we actually get
What is an LLM proxy?→
An LLM proxy is a server that receives the requests your app or coding agent would normally send straight to OpenAI, Anthropic or Google, and forwards them on your behalf. The simplest ones only forward. Once a proxy also routes between providers, tracks spend, applies rules and keeps logs, most vendors call it an LLM gateway or AI gateway. In practice the three terms describe the same position in the traffic; they differ in how much the product does while it is there.
What is an OpenAI compatible proxy?→
A proxy that accepts requests in OpenAI's API format (the chat completions shape most SDKs and tools already speak) and translates them for whichever model you choose. The benefit is that you change one base URL and one key, and the same code can call Claude, Gemini or an open model. LiteLLM, Portkey, Kong's AI Proxy plugin, Vercel AI Gateway and Cloudflare AI Gateway all offer an OpenAI-compatible endpoint; tools such as Claude Code that speak Anthropic's format need a gateway that accepts that format too.
What is LLM middleware?→
LLM middleware is the layer of logic that runs on a request between your application and the model: authentication, routing, retries and fallbacks, caching, spend limits, screening for prompt injection or personal data, and logging. A gateway is middleware that runs as a separate service, so every tool that points at it gets the same rules without each one being rebuilt.
What is a multi model API gateway?→
A gateway that gives you one key and one endpoint for models from several providers, so you can switch or fall back between OpenAI, Anthropic, Google and open models without new integrations. Vercel AI Gateway, Cloudflare AI Gateway, Portkey and LiteLLM are built around this. Constellation Gate AI routes to several providers as well, but leads with screening and the audit trail rather than catalogue size.
Is there an AI API gateway that is open source?→
Yes, several. LiteLLM is MIT-licensed and self-hosted with no licence fee. Portkey's gateway is MIT-licensed and runs locally with one npx command. Kong released its AI plugins, including AI Proxy and AI Prompt Guard, as free and open source from Kong Gateway 3.6. tamp is an MIT-licensed local compression proxy for coding agents. Open source removes the fee, not the work: you host, patch and monitor it yourself. Checked 23 September 2026.
Do I need an AI gateway if I only use one model?→
For routing, no: the provider's console gives you usage, spend limits and prompt caching. You need one when you want something the provider does not give you: screening of what goes in and comes out, a log you could show a client, a spend cap per agent or per person, fewer tokens per request, or one place to see what a whole team's tools are doing.
FILED ON THE AI VIDEO & REPURPOSING SHELF — MORE FIELD-TESTED TOOLS AND GUIDES THERE →
#AI#Marketing Stack#AI security#Claude#ChatGPT#productivity
Never miss a verdict
One tool tested, one workflow, one future signal, one deal — every week.
One email with the goods, then the weekly letter. Unsubscribe anytime.
Keep reading
Artificial Intelligence
Codex CLI Proxy: How to Route Codex Through a Gateway, and What a Codex Turn Actually Costs
Codex CLI sends its requests wherever ~/.codex/config.toml tells it to. One table in that file puts a gateway in the path, and one line inside that table decides whether you keep your ChatGPT plan or start paying per token. Here is the setup, the rule that decides your bill, what a Codex turn costs on each path, seven ways to spend less, and the difference between Codex Security and a gateway.
SEP 2026 · 12 MINREAD →
Artificial Intelligence
AI Audit Trail: The Receipt Your Clients Will Ask For, and Why a Chat History Is Not One
Clients are starting to ask what the AI did with their material. A screenshot is not an answer, and neither is a chat history the tool itself can rewrite. This is what an AI audit trail is, what makes a log verifiable rather than just stored, what one entry should contain, and how a freelancer or small agency hands a client the receipt without handing over the prompts.
SEP 2026 · 12 MINREAD →